Karaoke Mode
A sing-along feature for Spotify, designed around the person who says no. Vocal attenuation, synchronized lyrics, and a permission model that treats refusal as a first-class path.
Origin
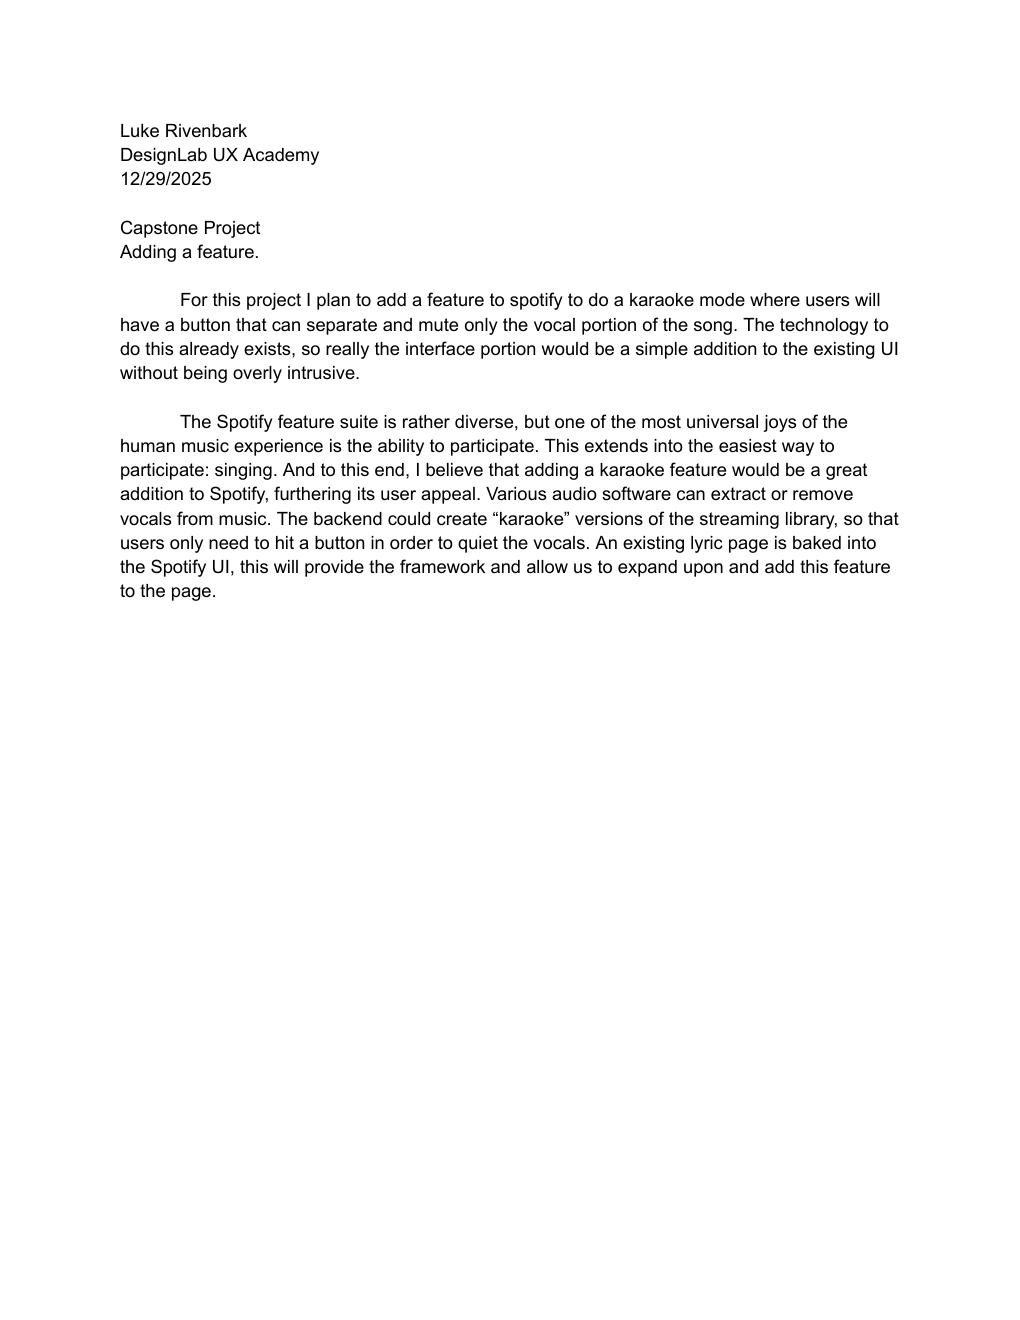
The feature was selected by one criterion: personal stake. The mentor's directive — choose something the designer cares about and would use — resolved a brainstorm into a single candidate. Karaoke was recent, real, and unserved. The brief is three paragraphs. The mentor's approval note calls it a simple brief and a great idea. Both statements are correct.
Process, taken straight
A first capstone is for learning the process, not renegotiating it. The curriculum ran on rails by choice: brief, competitive analysis, interview guide, interviews, synthesis, definition, wireframes, mockups, testing. Deviation is a tool. It was deliberately left in the drawer.
The competitive gap
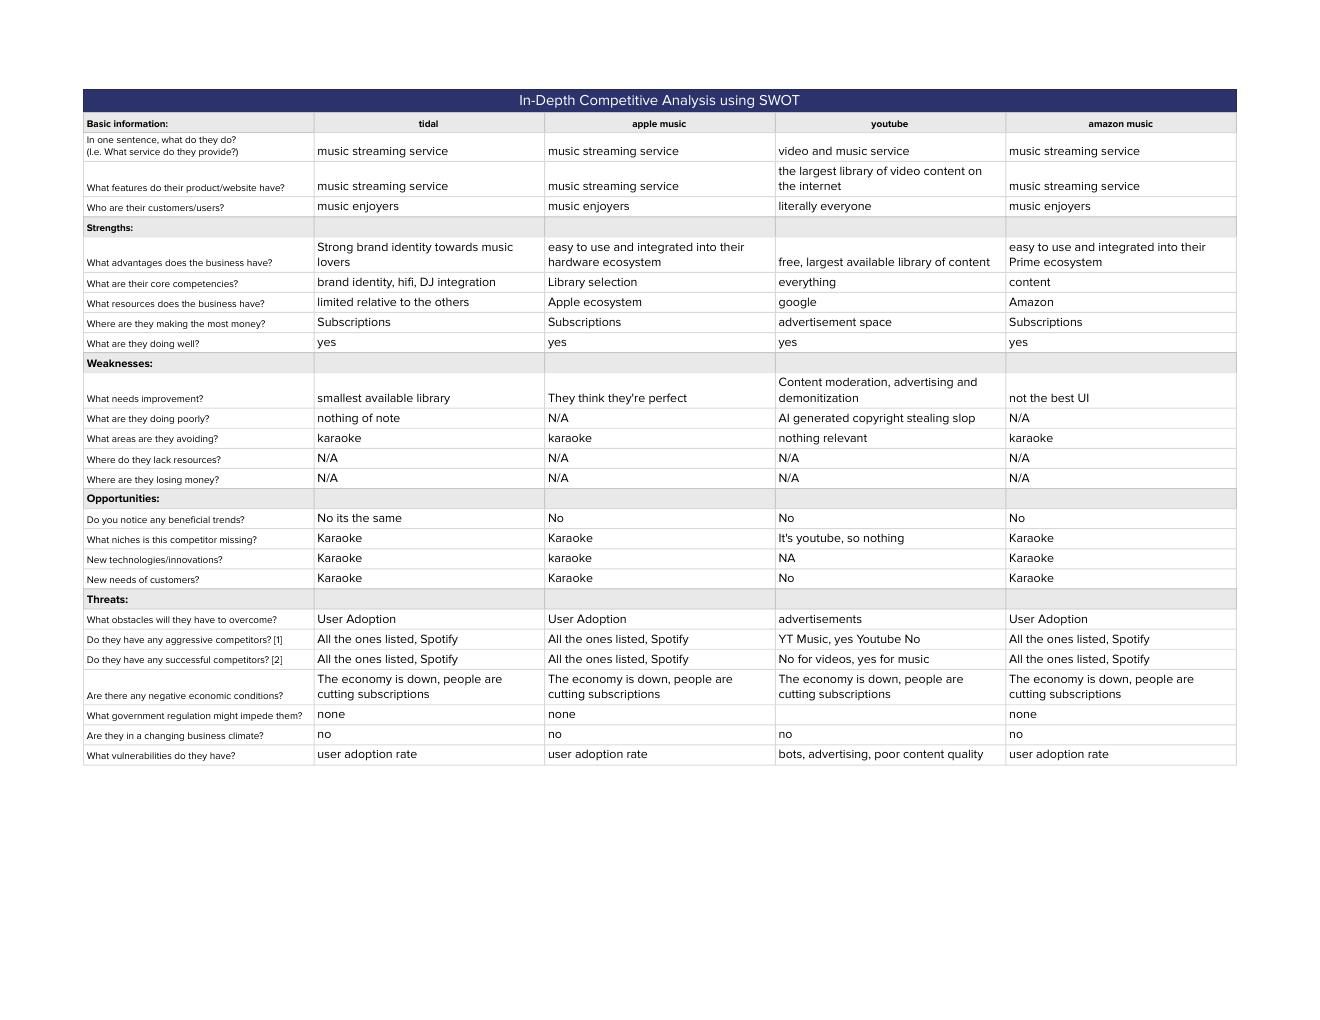
No major streaming service ships an integrated karaoke mode. YouTube wins the use case by accident of structure — music videos with lyric overlays uploaded by third parties. The gap is real; the analysis confirmed rather than redirected. The mentor's extension note — audit competitors for accessibility features — is logged as method for future analyses.
Research under friction
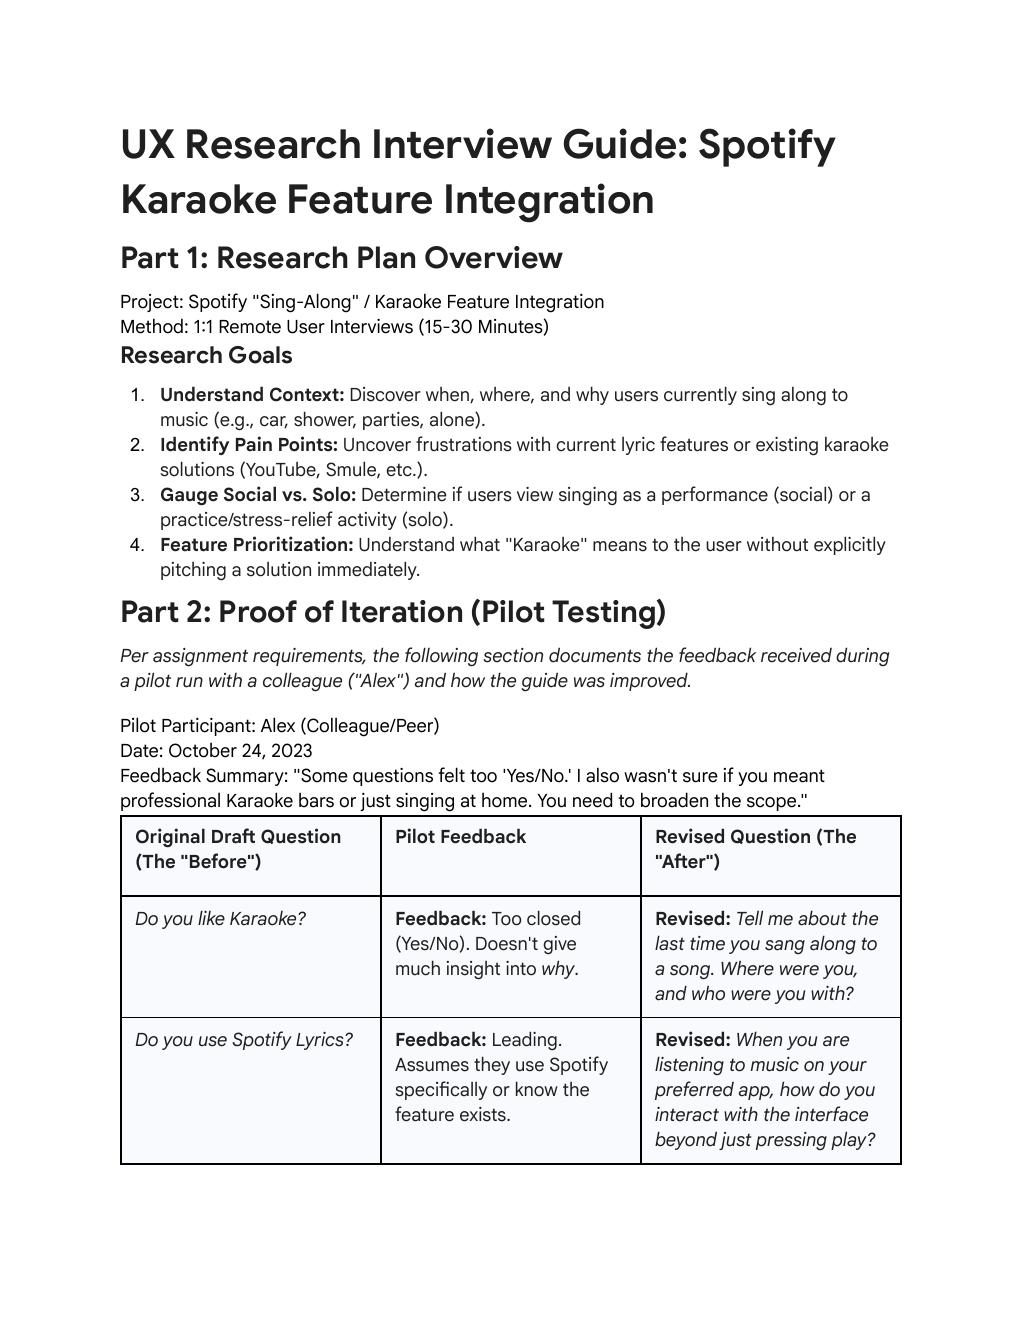
The interview guide went through one same-day iteration loop: mentor question-adds, changes bolded for review speed, approved within hours. The field period did not move at that speed. Recruiting and scheduling moderated sessions stretched across weeks. The response was instrumental, not heroic: when scheduling fails, change the instrument. The async pivot entered the toolkit here and never left it.
Honest data
Most recruited participants were not Spotify users. The submission note states the limitation plainly; the mentor's approval resolves it — interest in karaoke, not platform loyalty, is the variable under test. The panel was accepted as imperfect and useful. Pretending otherwise would have produced prettier data and a weaker study.
The insight: vocal shame
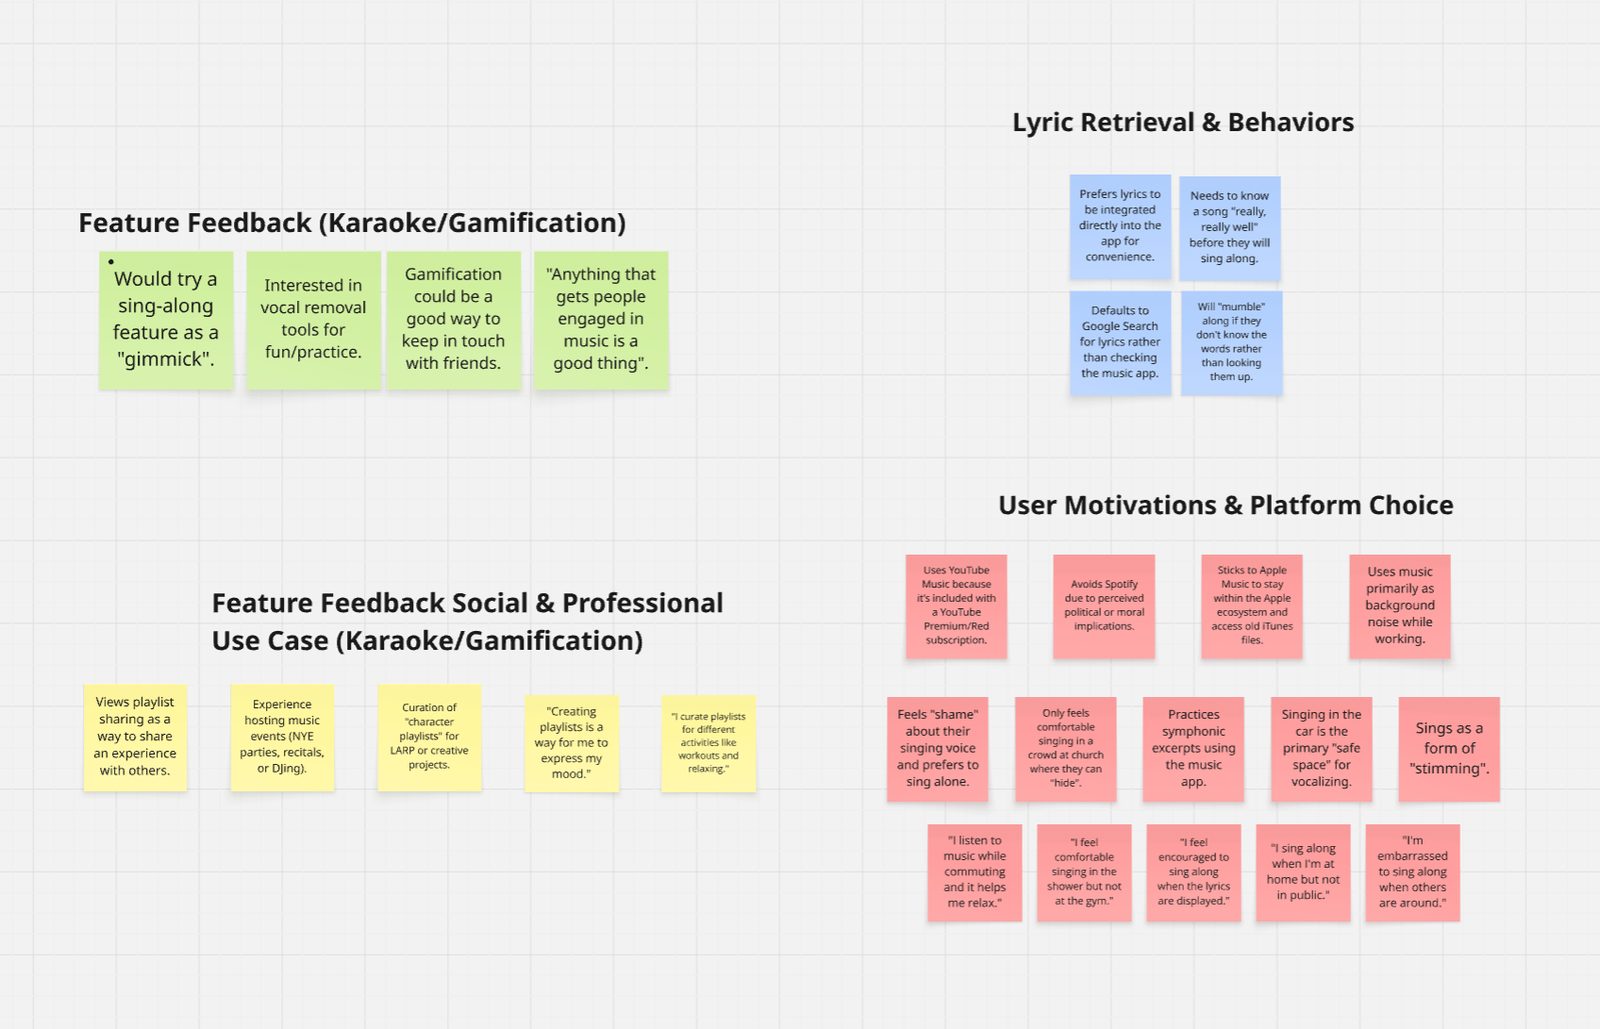
Interviews confirmed the founding hypothesis and sharpened it. Users love music, want to sing, and restrict singing to safe spaces — the car, the shower. The inhibitor is not capability; it is the fear of being heard. The design brief that emerged: build a low-pressure environment that bridges desire and fear. Solo-first, not gated behind group sessions — a ruling the mentor endorsed explicitly.
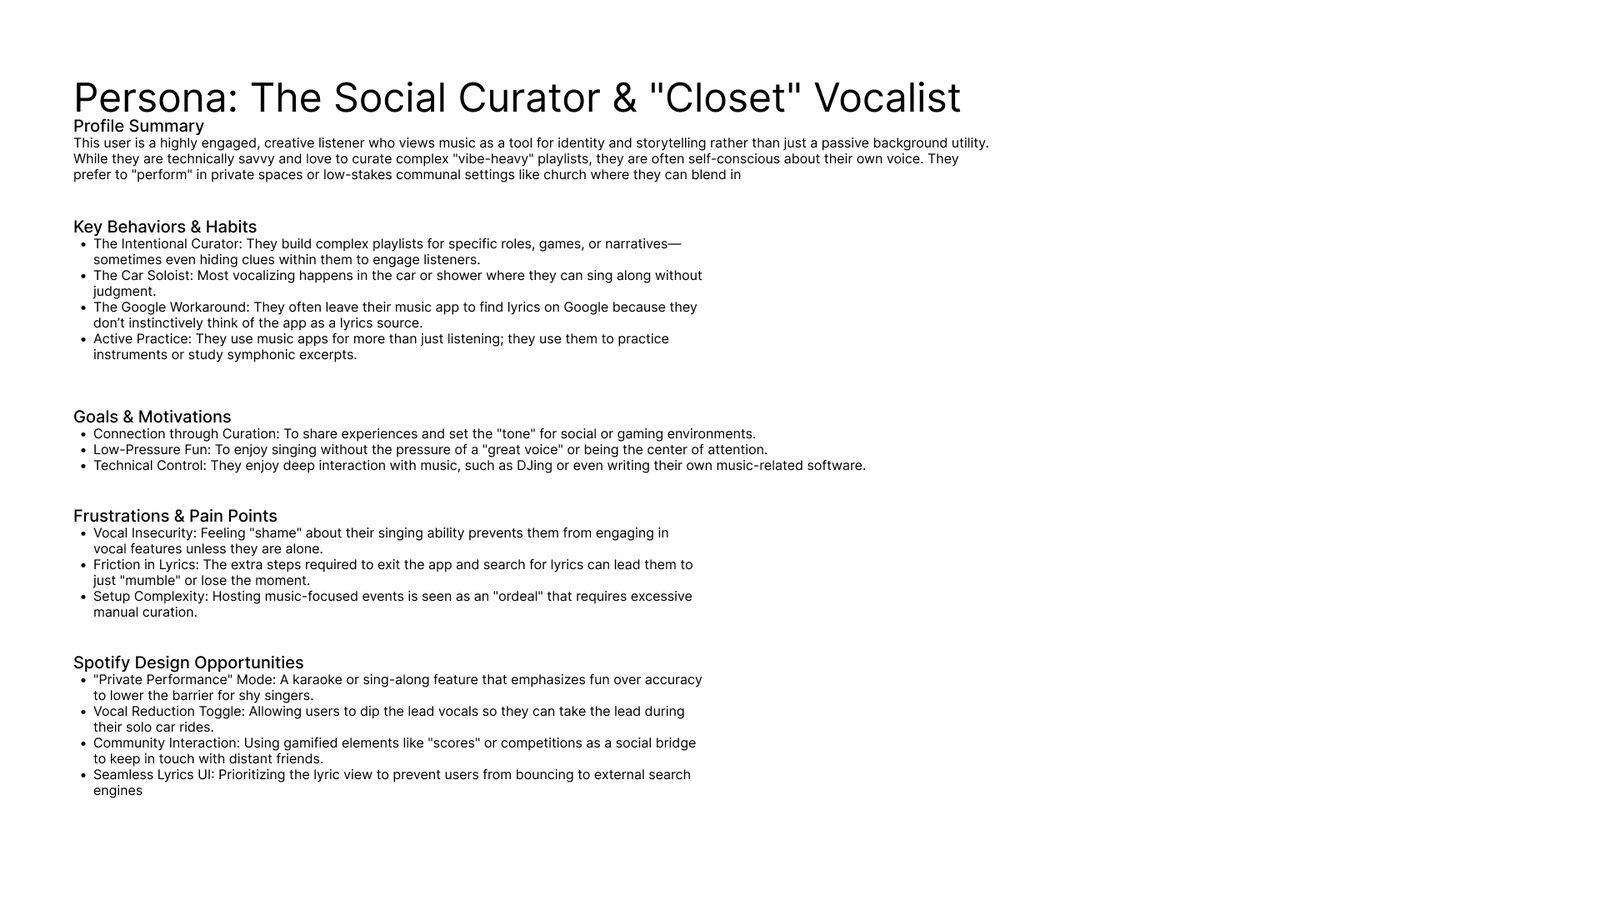
Design for the person who says no
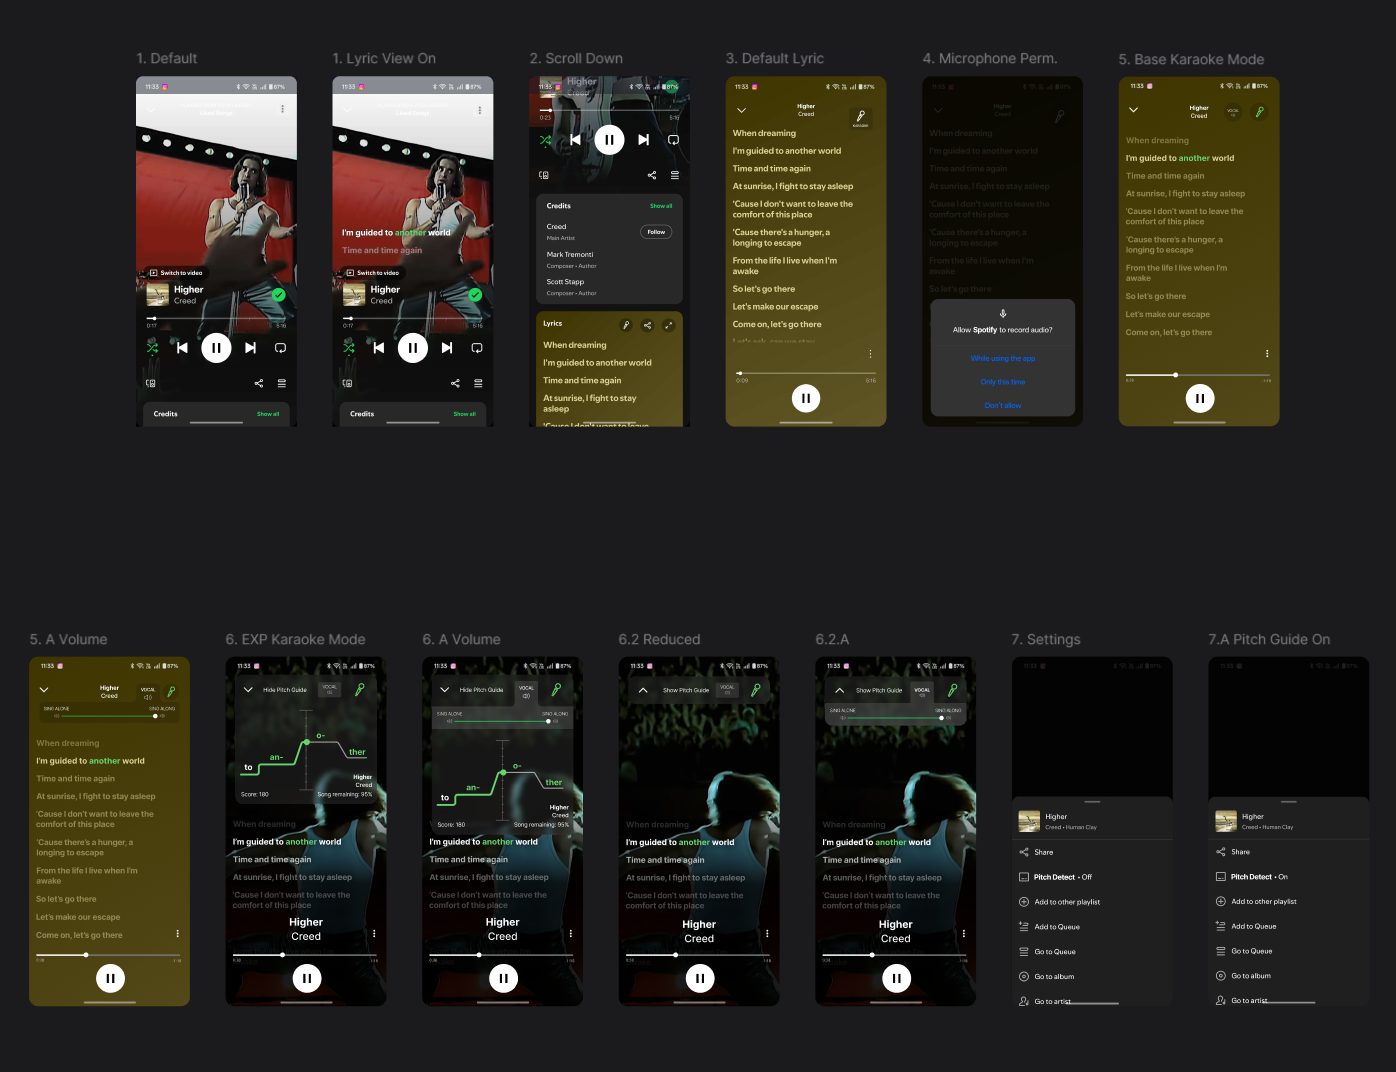
Microphone-permission denial was specified as a first-class path from conception, not patched in after testing. The reasoning is layered: privacy anxiety deserves respect; loud rooms corrupt pitch scoring; microphones break; a user on a call may still want lyrics. Real-world karaoke does not grade its singers. The no-mic path mimics the YouTube experience — adjustable vocals, synchronized lyrics, no judgment. Flexibility was the principle; the permission fork is its implementation.
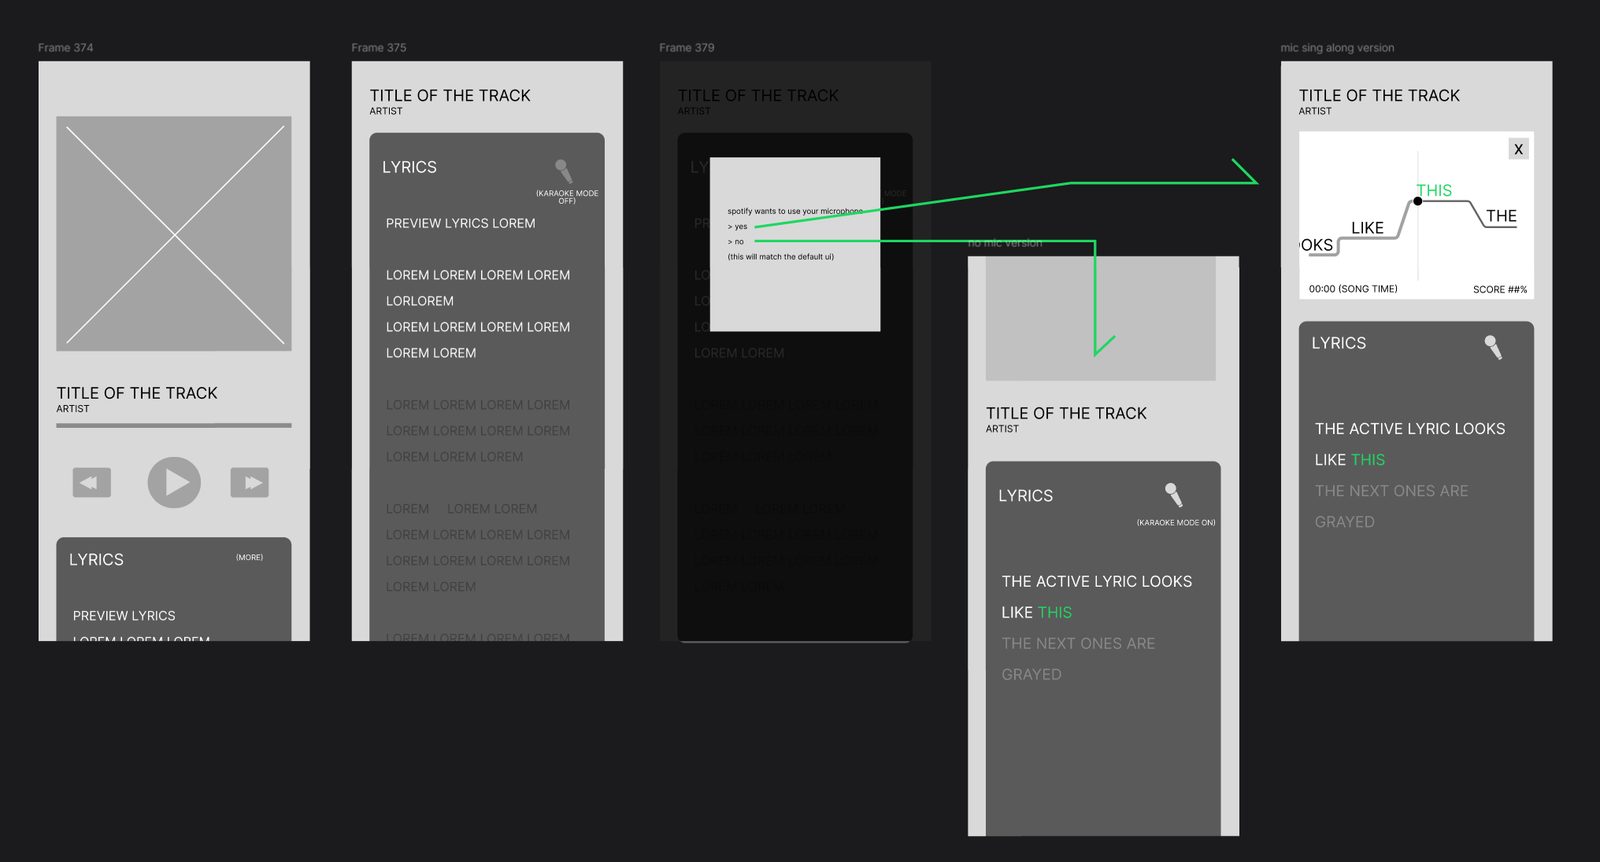
A feature from a participant's mouth
The signature control — partial vocal attenuation rather than binary mute — originated in an interview. The original vocal, dipped but present, functions as an audio cue for lyric recall. If the system already separates stems, attenuation is free. The feature was specified, then nearly lost: a pre-test document review on 04/01 caught its omission from the hi-fi build and restored it. The review ritual paid for itself in one catch.
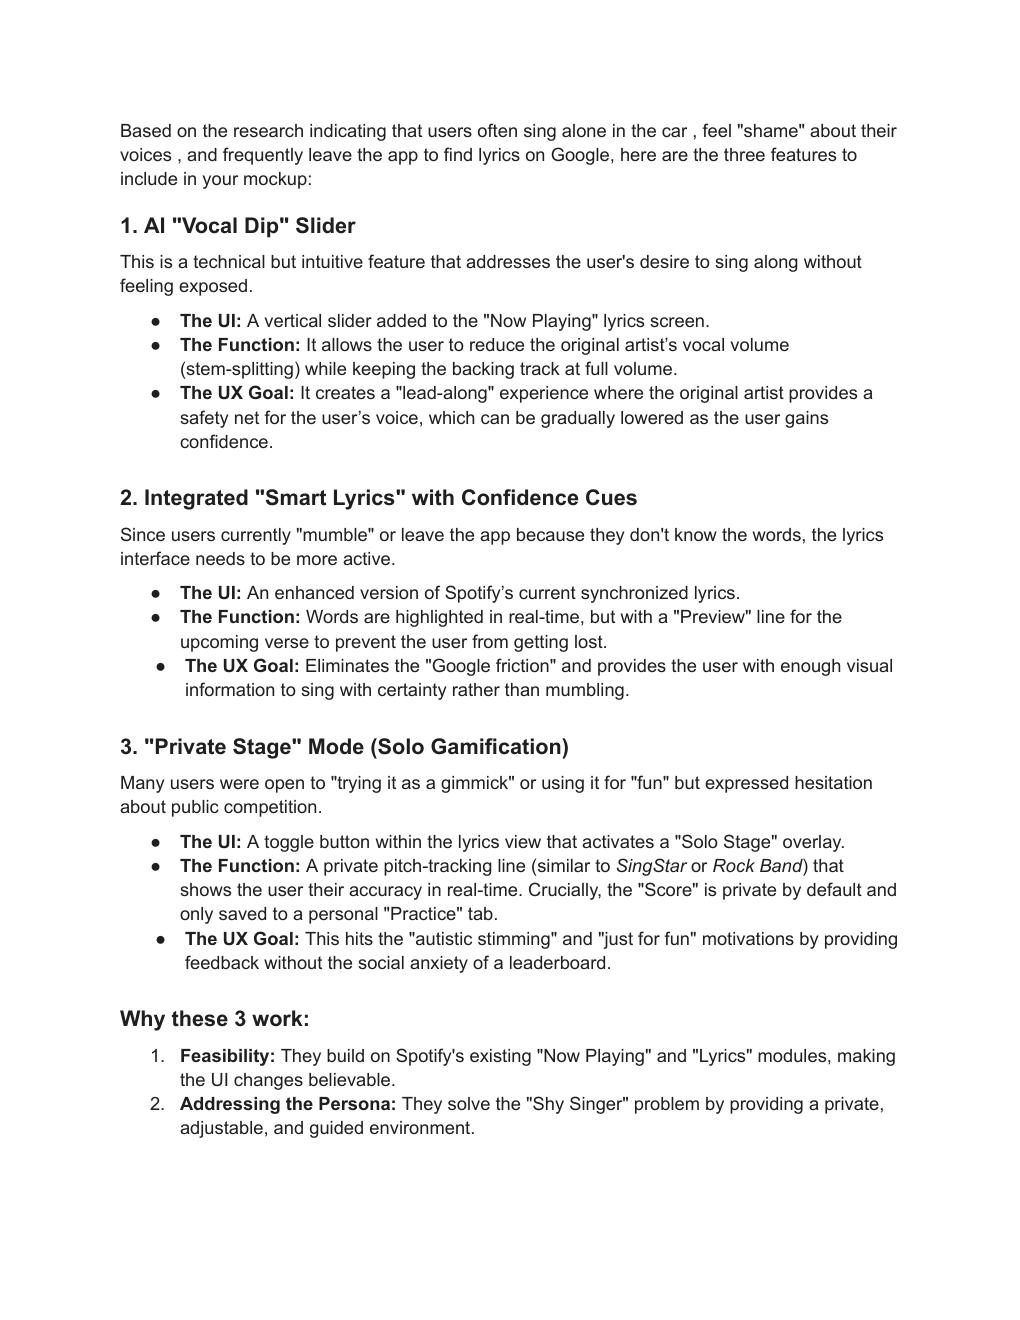
Borrowed wheel, hand-matched
The screens were built inside Spotify's design language, not against it. A community UI kit supplied components; the real lyric-tab screenshot supplied truth. Spacing, tracking, and kerning were matched by hand-overlay against the live app. One editorial swap: the demo track moved from The Beatles to Creed — partly meme, partly method, because studying the live app surfaced the music-video background pattern that real karaoke convention expects, and the new track demonstrated it.
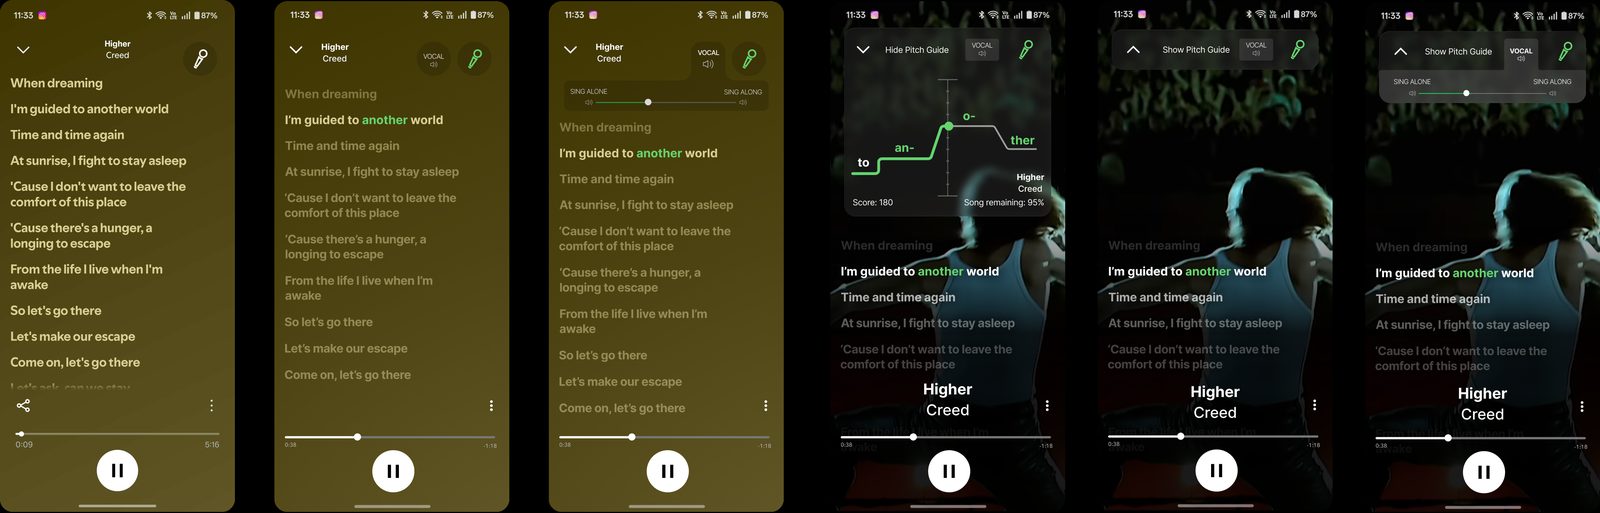
The animation wall
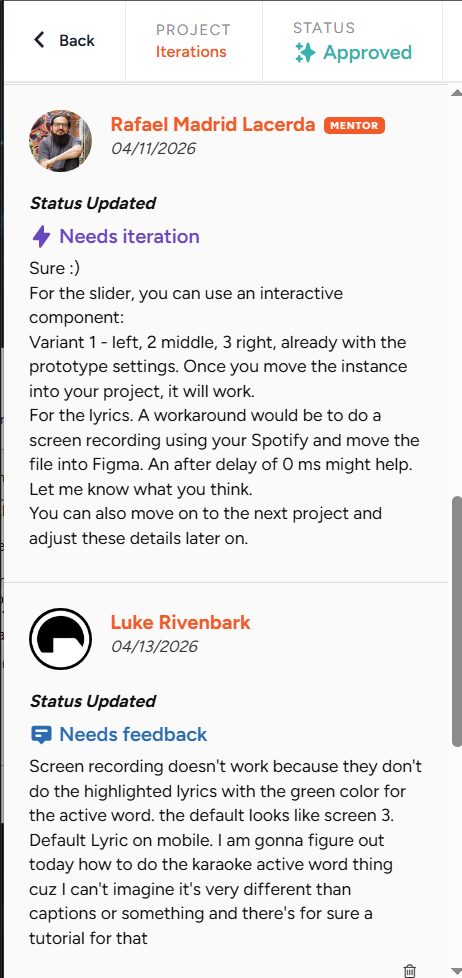
The mockups earned a challenge from the mentor: without motion, the prototype reads as a slideshow. What followed is documented in five moves. A tutorial-built slider failed — full-max or nothing. The mentor's workaround, screen-recording the live app into Figma, was rejected on technical grounds: recordings lack the green active-word treatment that defines the karaoke read. A captions-style approach was attempted. Figma Make — then brand new — was trialed and abandoned within a day. The prototype shipped without full motion, deferred to a pre-portfolio pass, with the mentor's concurrence. Perfectionism lost the schedule argument, on purpose.
Testing, two instruments
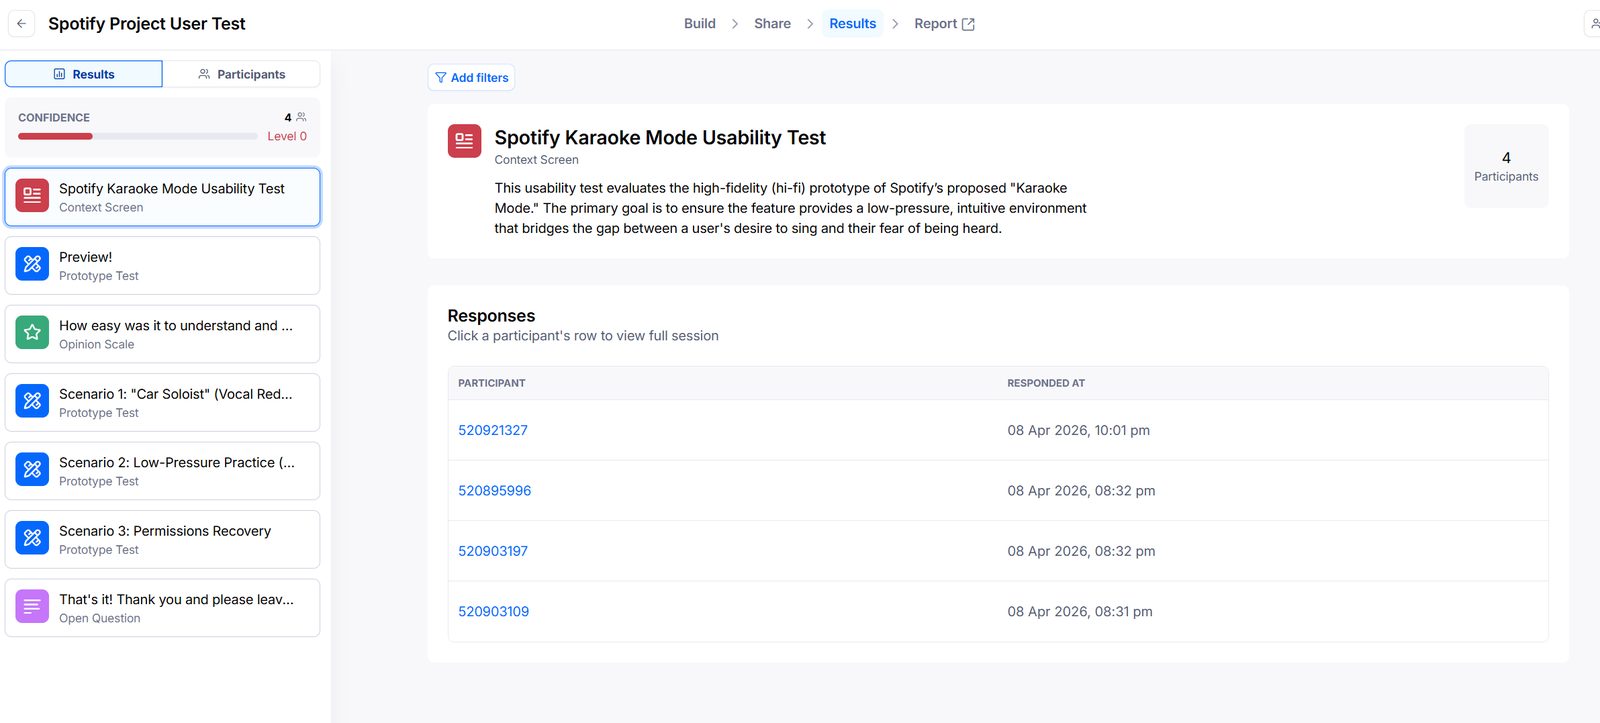
The lo-fi round ran as designed: five moderated remote think-aloud sessions, ~30 minutes each. Users navigated entry points without help; the pitch-tracking representation and the permissions-denied flow needed work — the missing interstitial screens were built in response. The hi-fi round ran on the async instrument after scheduling friction returned. A Maze deployment also ran; its data no longer exists — the free tier permits one project, and creating the next capstone's test destroyed this one's record. The lesson matured two capstones later into owned instrumentation.
What it seeded
The augmented workflow began here: stream-of-consciousness drafts plus data plus rubric, edited into deliverables by machine, verified and submitted by hand. The mentor named it on the record — a good mix between handmade and AI work — and twice recommended the tool that would eventually replace the whole stack. Three practices left this project alive: the async pivot, ship-over-perfectionism, and the habit of auditing tools by their failures. All three became infrastructure.